
A Baidu-affiliated research group just spelled out why classic SEO scorecards misfire on generative answers. The preprint From Ranked Documents to Reliable Contexts (authors include Baidu Inc. researchers, with Yinqiong Cai as corresponding author, plus Chinese Academy of Sciences / UCAS / Wuhan University collaborators) argues that Search Satisfaction axes — relevance, authority, freshness, quality — are a poor match for model-facing AI search. Models need answer support, trustworthiness and organised context, not another ten-blue-links beauty contest.
The proposed stack is three-stage: Answer Support, Content Trustworthiness, and Context Organization, with a prior-plus-posterior optimisation workflow and industrial experiments. Coverage on NetContentSEO (citing a 23 September 2026 revision) lists author-reported component lifts that are useful as directional evidence, not as Baidu’s live ranking spec: source-role modelling vs static authority (+5.2pp automatic answer pass / 2.7% human Net Gain); content-time vs publication time (+4.1pp / 3.5%); query expiration modelling (+3.0pp / 2.4%); claim verification (+4.8pp high-quality result-set rate, +3.9pp auto pass, 4.2% Net Gain); extractive passage refinement (+4.1pp auto pass and 8.9% human Net Gain — the largest human gain in the reported table); set-wise organiser (+7.2pp query usability, +1.8pp auto pass, 1.0% Net Gain).
Read that carefully. The paper does not claim this entire pipeline is Baidu Search’s production end-to-end ranker. It does claim industrial implementation and online component experiments. That is enough for SEOs to update the content brief: verifiable, time-valid, extractable evidence beats keyword overlap theatre when the consumer is a generator assembling an answer set.
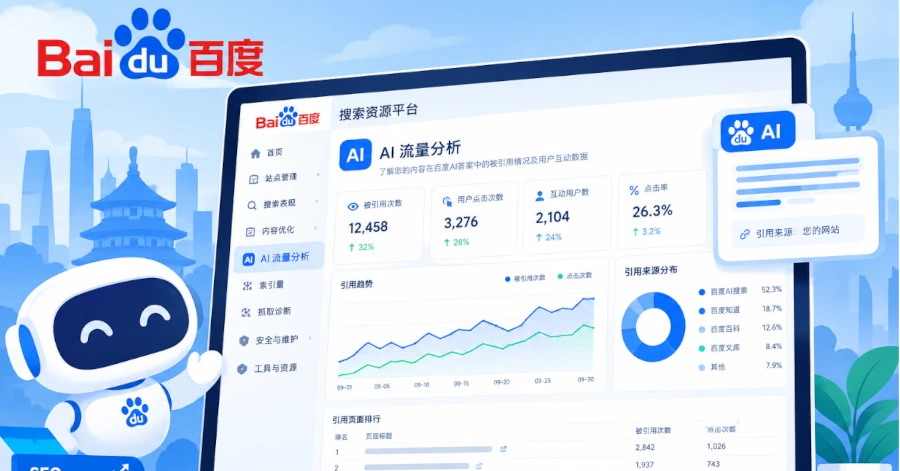
Pair this with Baidu’s separate AI Traffic Analysis webmaster panel (citations/impressions/clicks for in-SERP AI answers) and you get a coherent China story: Baidu is instrumenting citation visibility on one side and publishing research that says citation-worthy pages look like evidence packs on the other. International brands still obsessing over Baidu “weight” folklore should spend a quarter building quotable facts with clear timestamps instead.
Opinionated advice: rewrite money pages so a model can lift a claim, a date and a source without scraping marketing fluff. That helps Alice, Qwen agents and Google AI Overviews too — which is the point. Evidence fitness is becoming the shared GEO substrate even when engines refuse to share a ranking document.
Also note what the paper implies for Baidu Tongji and Webmaster workflows. Citation dashboards without evidence hygiene just teach you which thin pages got lucky. Use the industrial framing as an editorial checklist: does each money URL state who claims what, when it was true, and which passage a model can lift without the surrounding brand essay? If not, you are optimising for a relevance world Baidu’s own researchers say is the wrong objective for AI search.